📋 KEY INSIGHTS
- Spatial data science applies statistical and ML methods to data with explicit geographic location — points (stores, events), lines (roads, rivers), polygons (neighbourhoods, countries), or raster grids (satellite imagery). The fundamental challenge is Tobler’s First Law of Geography: “everything is related to everything else, but near things are more related than distant things.” Standard ML models assume IID observations and fail to leverage or account for this spatial dependence, producing biased estimates and invalid standard errors.
- GeoPandas is the foundational Python library for spatial data science: it extends pandas DataFrames with a geometry column (storing shapely Point, LineString, or Polygon objects in WGS-84 or projected CRS), enabling spatial operations (spatial join, buffer, dissolve, intersection) using a pandas-like API. A GeoDataFrame is a standard pandas DataFrame that can also plot maps (via matplotlib), reproject between coordinate reference systems (CRS), and compute spatial statistics (area, centroid, distance).
- Spatial joins connect datasets based on geographic relationships rather than shared keys: a within join assigns each point to the polygon it falls within (assigning census tracts to points of interest); a nearest join finds the nearest feature in a target dataset for each feature in a source dataset; a within-distance join finds all features within a specified radius. Spatial joins are the geospatial equivalent of SQL JOINs and are the primary data integration operation in spatial data science.
- Spatial autocorrelation — the tendency of nearby observations to have similar values — violates the independence assumption of standard regression and classification models, inflating precision estimates and producing spurious significance. Moran’s I statistic measures global spatial autocorrelation (whether high-value regions cluster together); Local Moran’s I (LISA) identifies local spatial clusters (hot spots and cold spots). Accounting for spatial autocorrelation requires spatial regression models (spatial lag model, spatial error model) or spatial cross-validation that prevents information leakage between geographically proximate train and test observations.
- Kriging (Gaussian Process regression on spatial coordinates) is the foundational geostatistical interpolation method: it predicts the value of a spatially varying field (soil contamination, temperature, rainfall) at unobserved locations by modelling the spatial covariance structure via a variogram (the half-expected-squared-difference between observations as a function of separation distance). Ordinary Kriging produces BLUE (Best Linear Unbiased Estimator) predictions at unobserved locations and provides uncertainty estimates (kriging variance) that quantify prediction uncertainty — analogous to the posterior variance of a Gaussian process.
- Spatial machine learning on graph-structured spatial data uses Graph Neural Networks where nodes are locations (census tracts, road segments, grid cells) and edges connect spatially adjacent or nearby nodes. This directly extends our GNN and GAT architectures to spatial settings: the spatial weight matrix (defining who is adjacent to whom) serves as the adjacency matrix, and spatial features (demographics, infrastructure, environmental variables) serve as node features. GNN-based spatial models capture non-linear spatial interactions that linear spatial regression models miss.
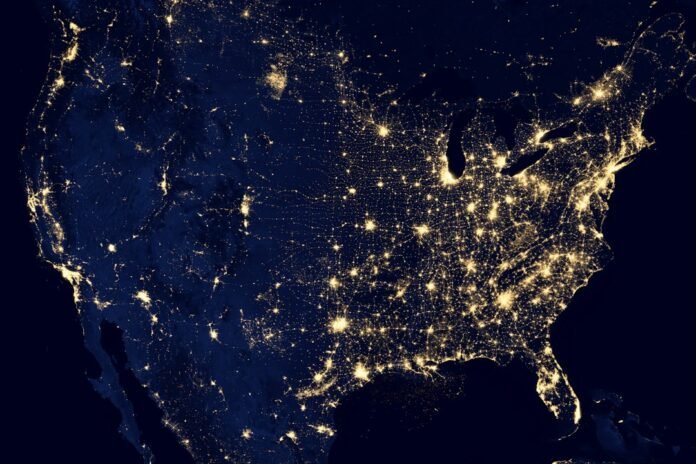
An enormous fraction of real-world data has an implicit spatial dimension: customer purchases are made at physical locations, crime events occur at specific addresses, disease cases are tied to patients’ home neighbourhoods, infrastructure failures are co-located on road networks, and satellite imagery provides pixel-level measurements of the entire Earth’s surface. Spatial data science is the discipline of analysing and modelling this geospatially located data — treating location not just as a feature to be one-hot encoded, but as a structured dimension that fundamentally shapes statistical relationships via geographic proximity and spatial autocorrelation. This guide covers the spatial data science toolkit: GeoPandas for spatial data manipulation, spatial joins and map visualisation, spatial autocorrelation (Moran’s I, LISA), spatial regression, kriging and interpolation, and spatial ML with GNNs — connecting these to the broader DS tools and methods covered across this blog.
GeoPandas, CRS and Spatial Operations
GeoPandas is the entry point for spatial data science in Python. A GeoDataFrame is a pandas DataFrame with a geometry column storing shapely geometries — Points for locations, LineStrings for paths, Polygons for regions. The most important operation is coordinate reference system (CRS) management: geographic data must be reprojected to a common CRS before any distance or area computation. WGS-84 (EPSG:4326) stores coordinates as decimal degrees (latitude, longitude) and is the universal interchange format (used by GPS, Google Maps, GeoJSON). For distance computations, data must be projected to a local planar CRS (UTM zone, Lambert, etc.) that minimises distortion in the region of interest — computing distances in decimal degrees produces incorrect results because a degree of longitude varies from ~111 km at the equator to 0 km at the poles. The connection to our data engineering fundamentals guide is direct: spatial data pipelines face the same ETL challenges as standard data pipelines (format normalisation, schema validation, join operations) plus the additional CRS management layer.
import geopandas as gpd, pandas as pd
# Load a shapefile of US census tracts and a CSV of business locations
tracts = gpd.read_file("census_tracts.shp").to_crs(epsg=3857)   # Web Mercator
businesses = gpd.GeoDataFrame(pd.read_csv("businesses.csv"),
    geometry=gpd.points_from_xy(df.lon, df.lat), crs="EPSG:4326"
    ).to_crs(epsg=3857)
# Spatial join: assign each business to its census tract
joined = gpd.sjoin(businesses, tracts[["GEOID","geometry"]], how="left", predicate="within")
# Buffer analysis: count businesses within 500m of each hospital
hospitals_buffered = hospitals.buffer(500)   # 500 metres in projected CRS
Spatial joins are the most important operation for enriching point-level event data with areal attributes. Common spatial join predicates: within (point in polygon), intersects (any geometric overlap), contains (polygon contains geometry), nearest (with gpd.sjoin_nearest). Spatial joins power many real-world feature engineering workflows: joining store transaction points to census demographic polygons to build household income and population density features, joining weather station points to farm field polygons to compute average rainfall for each field, or joining disease case points to neighbourhood polygons for epidemiological analysis. The connection to our feature engineering guide is direct: spatial joins are the spatial-data equivalent of table joins in the feature engineering pipeline.
| Operation | GeoPandas Method | Use Case |
|---|---|---|
| Spatial join (point-in-polygon) | gpd.sjoin(… predicate=”within”) | Assign events to regions |
| Nearest join | gpd.sjoin_nearest(…, max_distance=…) | Match each point to nearest facility |
| Buffer | gdf.buffer(radius) | Count features within radius |
| Dissolve (aggregate polygons) | gdf.dissolve(by=”region”) | Merge sub-regions into regions |
| Spatial autocorrelation | libpysal + esda: Moran(y, w) | Detect spatial clustering |
| Kriging / interpolation | pykrige: OrdinaryKriging | Interpolate at unobserved locations |
Spatial Autocorrelation and Spatial Regression

Spatial autocorrelation — the correlation of a variable with itself across geographic space — violates the IID assumption of standard statistical models. If house prices in neighbouring census tracts are positively correlated (which they always are), then a standard OLS regression of house prices on attributes treats each tract as independent, underestimates the standard errors of coefficient estimates (producing spurious statistical significance), and ignores the spatial pattern as a predictive signal. Moran’s I statistic measures global spatial autocorrelation: I = (n / S₀) × (Σ_i Σ_j w_ij (x_i – x̄)(x_j – x̄)) / (Σ_i (x_i – x̄)²), where w_ij is the spatial weight between locations i and j (typically 1 if adjacent, 0 otherwise, row-standardised) and S₀ = Σ_i Σ_j w_ij. I ≈ 0 means no spatial autocorrelation; I > 0 means positive autocorrelation (clustering); I < 0 means negative autocorrelation (dispersion). The connection to our hypothesis testing guide is direct: the significance of Moran’s I is tested via a permutation test — randomly permuting the location labels many times and computing I for each permutation to build the null distribution.
Spatial regression models account for spatial dependence in two ways. The spatial lag model (SLM) adds a spatially lagged dependent variable (ρ × Wy, where W is the spatial weight matrix and y is the dependent variable) as a predictor, modelling contagion effects (my house price is influenced by my neighbours’ house prices). The spatial error model (SEM) assumes spatial dependence enters through the error term (ε = λWε + u), modelling unmeasured spatially correlated confounders. Both are estimated via maximum likelihood using the PySAL/spreg library. For ML-based spatial prediction, spatial cross-validation (blocking observations into contiguous spatial blocks and using block-level train/test splits) is essential to get honest out-of-sample estimates: standard random cross-validation gives inflated accuracy because nearby observations in the test set are “proxies” for nearby observations in the training set.
Kriging, Satellite Data and Spatial GNNs
Kriging (Gaussian Process spatial regression) interpolates a spatially varying field at unobserved locations using a variogram model fitted to the observed data. The variogram γ(h) = (1/2) E[(Z(s) – Z(s+h))²] measures how dissimilarity between observations grows with separation distance h. Common variogram models: spherical (linear growth up to a range, then flat), exponential (exponential growth to a sill), and Gaussian (smooth). Ordinary Kriging conditions on the fitted variogram to produce BLUP predictions and kriging variances (uncertainty estimates) at any unsampled location. The connection to our Gaussian Processes guide is direct: kriging is exactly Gaussian Process regression with a stationary covariance kernel k(h) = C – γ(h) derived from the variogram, and the kriging variance is the GP posterior variance. Pykrige (Python) and R’s gstat are the standard libraries.
Satellite imagery (Sentinel-2, Landsat, MODIS) provides rich spatial data for agriculture, environment, and infrastructure monitoring. Raster data is processed with rasterio (reading GeoTIFF files), numpy array operations, and ML models applied per pixel (pixel classification) or per field polygon (zonal statistics, then tabular ML). For large-scale satellite ML, deep learning on image chips (CNN or ViT patch classifiers) fine-tuned from foundation models (SatMAE, SpectralGPT) achieves the best accuracy. Spatial GNNs — GNN architectures where nodes are spatial locations and edges connect nearby locations — learn non-linear spatial interaction patterns that spatial lag regression misses, and are increasingly used for traffic forecasting, air quality prediction, and epidemiological modelling on spatial networks.
✦ SUMMARIZE THIS ARTICLE WITH AI
 ChatGPT
Feature engineering for spatial features (spatial joins, zonal statistics, distance features) is in our Feature Engineering guide. GNNs for spatial network models are in our Graph Neural Networks guide. Gaussian Processes for kriging uncertainty quantification are in our Gaussian Processes guide. Hypothesis testing for Moran’s I significance is in our Hypothesis Testing guide. Data visualisation for choropleth maps and spatial plots is in our Data Visualisation guide. Data engineering pipelines for spatial ETL are in our Data Engineering guide.


