📋 KEY INSIGHTS
- ML models degrade silently in production: unlike software bugs that cause immediate errors, model quality degradation is gradual and often goes undetected until business metrics decline significantly. Systematic ML monitoring — tracking prediction quality, input feature distributions, and output distributions in real time — is the discipline that catches degradation early and triggers remediation before it becomes a crisis.
- The three-layer monitoring framework covers all degradation modes: data drift monitoring (has the input distribution P(X) changed?), concept drift monitoring (has the relationship P(Y|X) changed?), and prediction quality monitoring (are the model’s predictions still accurate on real outcomes?). Each layer requires different signals and triggers different responses: data drift triggers feature pipeline review; concept drift triggers retraining; prediction quality degradation triggers immediate investigation.
- Population Stability Index (PSI) is the standard metric for detecting data drift in production: PSI = Σ (P_actual – P_expected) × ln(P_actual / P_expected), computed over histogram bins of a feature distribution. PSI < 0.1 indicates no significant shift; 0.1–0.2 indicates moderate shift requiring monitoring; PSI > 0.2 indicates major shift requiring immediate action. PSI is fast to compute, interpretable, and has well-established industry thresholds from credit risk modelling.
- Shadow deployment — running a new model version in parallel with the current production model, receiving the same inputs and logging predictions but not serving results to users — is the standard technique for validating new model versions before traffic promotion. Shadow mode decouples model evaluation from user impact, enabling production-realistic evaluation without risk, and is a prerequisite for progressive rollout strategies like blue-green deployment and canary releases.
- Service Level Objectives (SLOs) for ML systems must cover both operational metrics (latency p99, error rate, availability) and ML-specific metrics (prediction drift, data freshness, label delay). An ML system with 99.9% uptime but a 40% degraded model accuracy is failing its SLO just as surely as a system with high latency. Defining ML-specific SLOs and alerting on them is the critical practice that organisations skip when they treat ML systems like ordinary software services.
- The most important monitoring investment for most organisations is setting up delayed label pipelines: the ground truth labels for predictions (did the customer churn? did the transaction turn out to be fraud?) arrive hours, days, or weeks after the prediction. Systematically matching predictions to delayed ground-truth labels and computing rolling precision/recall/AUC on this matched set is the gold standard for production model quality monitoring, far more reliable than proxy metrics.
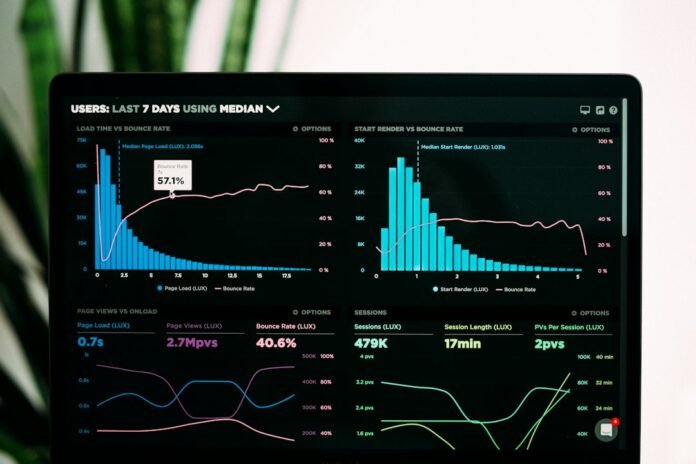
A model that passes all offline evaluations and deploys successfully can still fail silently in production. The fraud pattern that was prevalent in training data changes as fraudsters adapt. The user behaviour that drove churn predictions shifts after a product redesign. A data pipeline change alters a feature’s distribution, introducing a subtle mismatch between what the model was trained on and what it receives at inference time. Without systematic monitoring, these failures accumulate undetected until they surface as degraded business metrics — often weeks or months after they started. ML monitoring and observability is the engineering practice that makes model degradation detectable: defining what signals to track, setting thresholds that distinguish signal from noise, building pipelines that deliver ground-truth labels for retrospective evaluation, and connecting all of this to actionable alerting and automated retraining triggers. This guide covers the full monitoring stack: data drift detection (PSI, KL divergence, Kolmogorov-Smirnov), concept drift monitoring, prediction quality tracking with delayed labels, shadow deployment and progressive rollout, SLO definition for ML systems, and the major monitoring tools.
Data Drift Detection — PSI, KL Divergence and Statistical Tests
Data drift occurs when the distribution of input features in production diverges from the distribution seen during training. It is the most detectable form of model degradation because it requires no labels — only the input features available at prediction time. The monitoring pipeline computes drift statistics between a reference window (typically the training set or a recent stable production window) and a current window (the most recent N predictions) for each input feature.
Population Stability Index (PSI) is computed by binning a continuous feature into K bins (typically K=10 deciles based on the training distribution) and comparing the proportion of observations in each bin between the reference and current distributions: PSI = Σ_{k=1}^K (p_current_k − p_ref_k) × ln(p_current_k / p_ref_k). PSI originated in credit risk modelling and has well-established industry thresholds: PSI < 0.1 (no change), 0.1–0.2 (moderate shift, monitor closely), >0.2 (major shift, investigate immediately). PSI is asymmetric (PSI(P,Q) ≠ PSI(Q,P)) and sensitive to empty bins (add a small constant to avoid log(0)). The connection to our statistics fundamentals guide is direct: PSI is closely related to the KL divergence — PSI = KL(P_current || P_ref) + KL(P_ref || P_current) — and all the distributional comparison intuitions from information theory apply.
Statistical hypothesis tests for drift detection: the Kolmogorov-Smirnov (KS) test compares the empirical CDFs of two samples and is distribution-free; the chi-squared test compares binned categorical distributions; the Cramér-von Mises test is more sensitive than KS to differences in the tails. For high-dimensional feature spaces (hundreds of features), univariate drift tests suffer from multiple testing: a Bonferroni correction (divide the significance level α by the number of tests) or BH-FDR correction is required to control the false alarm rate, as covered in our hypothesis testing guide. Multivariate drift tests — Maximum Mean Discrepancy (MMD), domain classifier AUC — treat the drift detection problem as a two-sample test in the full feature space and are more sensitive to correlated feature shifts that univariate tests miss.
| Drift Type | What Changes | Detection Signal | Response |
|---|---|---|---|
| Data drift (covariate shift) | P(X) changes | PSI, KS test, MMD on input features | Investigate data pipeline; retrain |
| Label drift (prior shift) | P(Y) changes | Distribution of delayed ground truth labels | Adjust threshold; retrain |
| Concept drift | P(Y|X) changes | Prediction quality on delayed labels | Retrain with recent data |
| Prediction drift | Distribution of Ŷ changes | PSI on model output scores | Leading indicator; trigger investigation |
| Feature importance drift | SHAP values shift | SHAP distribution over time | Investigate feature relationships |
| Data quality drift | Null rates, range violations | Great Expectations / data contract checks | Fix data pipeline |
Shadow Deployment, Canary Releases and SLO Definition
Shadow deployment is the safest model promotion strategy: deploy the new model version to receive the same live traffic as the production model, compute its predictions, log them to a shadow store, but never serve them to users. The shadow model’s predictions are compared to the production model’s predictions (agreement rate, where they disagree and why) and retrospectively evaluated against delayed ground-truth labels. Only after the shadow model demonstrates equal or superior performance over a statistically significant evaluation window (typically 1–2 weeks of production data) does it get promoted to production. Shadow deployment decouples model risk from deployment risk: the engineering risk of deploying new model infrastructure is taken separately from the ML risk of serving new predictions. The connection to our MLflow model registry stage transition workflow is direct: the shadow deployment period corresponds to the Staging phase, and promotion to production corresponds to the Production stage transition, gated on the shadow evaluation results.
Canary releases route a small fraction of traffic (1–5%) to the new model while the majority continues to receive predictions from the current model. Unlike shadow mode, canary predictions are served to real users, making canary evaluation more realistic but also more risky. The standard canary escalation: 1% → 5% → 20% → 50% → 100%, with each escalation gated on the model meeting its SLO thresholds at the previous allocation. Feature flags (LaunchDarkly, Unleash) or service mesh routing (Istio, Envoy) implement the traffic splitting. The statistical framework for comparing model performance between canary and control — two-sample proportion tests for conversion metrics, bootstrap confidence intervals for continuous metrics — is exactly the A/B testing framework applied to model variants.
ML-specific SLOs extend the standard software reliability SLOs (latency p99 < 100ms, error rate < 0.1%, availability > 99.9%) with model quality commitments: prediction quality SLO (AUC on weekly delayed-label evaluation set > 0.85), data freshness SLO (feature store values < 5 minutes old for real-time features), drift SLO (PSI < 0.2 for all top-10 features), and prediction rate SLO (model returns a valid prediction for >99.5% of requests). SLO breaches trigger escalating responses: warning alerts at 80% of threshold, paging alerts at threshold breach, and automated fallback to a simpler backup model (rule-based or previous stable version) when the primary model is unavailable or severely degraded. The connection to our data quality guide is direct: ML monitoring SLOs are a superset of data quality SLOs, adding model-specific quality metrics on top of the data pipeline quality checks.
Delayed Label Pipelines and Retraining Triggers
Proxy metrics — prediction score distributions, click-through rates, error rates — are leading indicators of model degradation but are not the ground truth. The only true measure of model quality in production is evaluation against real outcomes. Building a delayed label pipeline is therefore the highest-value monitoring investment: instrument the prediction serving system to log every prediction with a unique prediction ID; instrument the outcome system (transaction processing, churn event logging, clinical outcome recording) to log the outcome with the prediction ID when it becomes available; join the two streams on prediction ID to compute realised prediction quality metrics on a rolling basis. The streaming ML infrastructure (Kafka, Flink, feature stores) is the natural substrate for this join: prediction events and outcome events flow through Kafka, and the join logic runs as a Flink stateful operator with a TTL (time-to-live) that matches the label delay window.
Retraining triggers should be automatic, not manual. The standard trigger conditions: (1) PSI > 0.2 on any top-10 feature; (2) Rolling AUC on delayed labels drops below the SLO threshold; (3) Prediction drift PSI > 0.2 on the model output score; (4) Scheduled retraining at a fixed cadence (weekly, monthly) as an insurance policy. Automated retraining pipelines — orchestrated with Airflow or Kubeflow Pipelines — re-run the full training pipeline on fresh data, evaluate the new model in shadow mode, and promote it through the MLflow registry stage-transition workflow when quality gates pass. The data contract checks on the fresh training data run before retraining begins, ensuring that a data pipeline failure does not cause a degraded model to be trained and promoted.
✦ SUMMARIZE THIS ARTICLE WITH AI
 ChatGPT
MLflow model registry and stage transitions that implement shadow deployment and promotion are in our MLflow guide. Data quality monitoring and data contracts that catch upstream data pipeline issues are in our Data Quality guide. A/B testing statistical framework applied to canary model evaluation is in our A/B Testing guide. Streaming ML infrastructure (Kafka, Flink) for delayed label pipelines is in our Streaming ML guide. SHAP feature importance drift monitoring is in our Model Interpretability guide. Statistical tests for drift detection — KS, chi-squared, multiple testing correction — are in our Hypothesis Testing guide.